 |
Block-Structured AMR Software Framework
|
|
Block-Structured AMR Software Framework
|
#include <AMReX_MLNodeLaplacian.H>
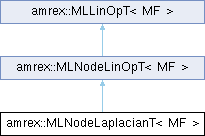
Public Types | |
| using | FAB = typename MLNodeLinOpT<MF>::FAB |
| using | RT = typename MLNodeLinOpT<MF>::RT |
| using | BCMode = typename MLNodeLinOpT<MF>::BCMode |
| using | StateMode = typename MLNodeLinOpT<MF>::StateMode |
| using | Location = typename MLNodeLinOpT<MF>::Location |
| using | CoarseningStrategy = typename MLNodeLinOpT<MF>::CoarseningStrategy |
| Public Types inherited from amrex::MLNodeLinOpT< MF > | |
| using | FAB = typename MLLinOpT<MF>::FAB |
| using | RT = typename MLLinOpT<MF>::RT |
| using | BCType = typename MLLinOpT<MF>::BCType |
| using | BCMode = typename MLLinOpT<MF>::BCMode |
| using | StateMode = typename MLLinOpT<MF>::StateMode |
| using | Location = typename MLLinOpT<MF>::Location |
| using | CoarseningStrategy = MLNodeLinOpCoarseningStrategy |
| Public Types inherited from amrex::MLLinOpT< MF > | |
| using | MFType = MF |
| using | FAB = typename FabDataType<MF>::fab_type |
| using | RT = typename FabDataType<MF>::value_type |
| using | BCType = LinOpBCType |
| using | BCMode = LinOpEnumType::BCMode |
| using | StateMode = LinOpEnumType::StateMode |
| using | Location = LinOpEnumType::Location |
Public Member Functions | |
| MLNodeLaplacianT ()=default | |
| Construct an empty operator; call define() before solving. | |
| MLNodeLaplacianT (const Vector< Geometry > &a_geom, const Vector< BoxArray > &a_grids, const Vector< DistributionMapping > &a_dmap, const LPInfo &a_info=LPInfo(), const Vector< FabFactory< FAB > const * > &a_factory={}, RT a_const_sigma=RT(0.0)) | |
| Convenience constructor without EB factories. | |
| MLNodeLaplacianT (const Vector< Geometry > &a_geom, const Vector< BoxArray > &a_grids, const Vector< DistributionMapping > &a_dmap, const LPInfo &a_info, const Vector< EBFArrayBoxFactory const * > &a_factory, RT a_const_sigma=RT(0.0)) | |
| Convenience constructor that accepts embedded-boundary factories. | |
| ~MLNodeLaplacianT () override=default | |
| MLNodeLaplacianT (const MLNodeLaplacianT &)=delete | |
| MLNodeLaplacianT (MLNodeLaplacianT &&)=delete | |
| MLNodeLaplacianT & | operator= (const MLNodeLaplacianT &)=delete |
| MLNodeLaplacianT & | operator= (MLNodeLaplacianT &&)=delete |
| void | define (const Vector< Geometry > &a_geom, const Vector< BoxArray > &a_grids, const Vector< DistributionMapping > &a_dmap, const LPInfo &a_info=LPInfo(), const Vector< FabFactory< FAB > const * > &a_factory={}, RT a_const_sigma=RT(0.0)) |
| Bind the nodal operator (no EB data). | |
| void | define (const Vector< Geometry > &a_geom, const Vector< BoxArray > &a_grids, const Vector< DistributionMapping > &a_dmap, const LPInfo &a_info, const Vector< EBFArrayBoxFactory const * > &a_factory, RT a_const_sigma=RT(0.0)) |
| std::string | name () const override |
| bool | supportsMixedPrecision () const override |
| void | setRZCorrection (bool rz) noexcept |
| Enable cylindrical (RZ) metric terms. | |
| void | setBoundaryDivuCorrection (bool on) noexcept |
| Second-order nodal divergence at nodes on Neumann and inflow domain faces. | |
| void | setNormalizationThreshold (RT t) noexcept |
| Threshold for normalization (prevents dividing by tiny averages). | |
| void | setSigma (int amrlev, const MF &a_sigma) |
| Provide per-level conductivity (cell-centered MultiFab). A multi-component input also triggers mapped-coordinate mode. | |
| void | spForwardSigma () |
| void | compDivergence (const Vector< MF * > &rhs, const Vector< MF * > &vel) |
| Compute rhs = div(vel) on nodal grids (used for projections). | |
| void | compRHS (const Vector< MF * > &rhs, const Vector< MF * > &vel, const Vector< const MF * > &rhnd, const Vector< MF * > &rhcc) |
| Assemble RHS including nodal/cell-centered forcing terms. | |
| void | updateVelocity (const Vector< MF * > &vel, const Vector< MF const * > &sol) const |
| Update velocities using the Poisson solution (projection correction). | |
| void | compSyncResidualCoarse (MF &sync_resid, const MF &phi, const MF &vold, const MF *rhcc, const BoxArray &fine_grids, const IntVect &ref_ratio) |
| Build coarse-level sync residuals for multilevel projections. | |
| void | compSyncResidualFine (MF &sync_resid, const MF &phi, const MF &vold, const MF *rhcc) |
| Build fine-level sync residuals for multilevel projections. | |
| void | setGaussSeidel (bool flag) noexcept |
| Choose red-black Gauss-Seidel instead of Jacobi smoothing. | |
| void | setHarmonicAverage (bool flag) noexcept |
| Toggle harmonic averaging when coarsening sigma. | |
| void | setMapped (bool flag) noexcept |
| Enable mapped-coordinate metrics (non-orthogonal grids). | |
| void | setCoarseningStrategy (CoarseningStrategy cs) noexcept |
| Pick between sigma-weighted or RAP coarsening (ignored if sigma constant). | |
| BottomSolver | getDefaultBottomSolver () const final |
| void | restriction (int amrlev, int cmglev, MF &crse, MF &fine) const final |
Restrict nodal data from fine grids to coarse MG level cmglev. | |
| void | interpolation (int amrlev, int fmglev, MF &fine, const MF &crse) const final |
Add the prolongation of coarse data onto the fine grid (fine += prolong(crse)). | |
| void | averageDownSolutionRHS (int camrlev, MF &crse_sol, MF &crse_rhs, const MF &fine_sol, const MF &fine_rhs) final |
Average solution/RHS pairs from fine AMR levels onto (camrlev). | |
| void | interpCoarseFineSolution (int famrlev, MF &fine_sol, const MF &crse_sol) const final |
Set the coarse/fine nodes of fine AMR level famrlev (Dirichlet mask set, not on a Dirichlet domain face) to the interpolated coarse solution, so that the composite solution does not depend on the initial guess there. Known nodes of an overset mask are kept. | |
| void | reflux (int crse_amrlev, MF &res, const MF &crse_sol, const MF &crse_rhs, MF &fine_res, MF &fine_sol, const MF &fine_rhs) const final |
Flux register reflux coupling coarse/fine nodal solves (updates res using the solution and RHS arrays on both levels). | |
| void | prepareForSolve () final |
| Finalize metric terms, sigma averages, and BC caches before solving. | |
| bool | needsUpdate () const final |
| True if sigma-derived data need to be refreshed before reuse. | |
| void | update () final |
| Refresh sigma averages/stencils and clear the dirty flag. | |
| void | Fapply (int amrlev, int mglev, MF &out, const MF &in) const final |
Apply the nodal Laplacian to in at (amrlev,mglev). | |
| void | Fsmooth (int amrlev, int mglev, MF &sol, const MF &rhs) const final |
Execute the smoother on (amrlev,mglev). | |
| void | normalize (int amrlev, int mglev, MF &mf) const final |
Divide mf by the diagonal of the operator (used by CG-family bottom solvers). | |
| void | fixUpResidualMask (int amrlev, iMultiFab &resmsk) final |
| Adjust residual masks so EB Dirichlet nodes remain constrained. | |
| void | getFluxes (const Vector< Array< MF *, 3 > > &a_flux, const Vector< MF * > &a_sol, Location a_loc) const final |
| This overload is unused for nodal Laplacians (only cell-centered flux extraction is supported). | |
| void | getFluxes (const Vector< MF * > &a_flux, const Vector< MF * > &a_sol) const final |
| Compute face-centered fluxes given nodal solutions. | |
| void | unimposeNeumannBC (int amrlev, MF &rhs) const final |
Remove Neumann contributions previously imposed on rhs. | |
| Vector< RT > | getSolvabilityOffset (int amrlev, int mglev, MF const &rhs) const override |
| Compute component-wise offsets needed for solvability enforcement. | |
| void | fixSolvabilityByOffset (int amrlev, int mglev, MF &rhs, Vector< RT > const &offset) const override |
Subtract solvability offsets from rhs. | |
| void | compGrad (int amrlev, const Array< MF *, 3 > &grad, MF &sol, Location loc) const final |
| Unsupported flux-style gradient extractor (kept for interface completeness). | |
| void | compGrad (int amrlev, MF &grad, MF &sol) const |
Compute gradients of sol into nodal MultiFab grad on AMR level amrlev. | |
| void | averageDownCoeffs () |
| Average conductivity down across all AMR and MG levels. | |
| void | averageDownCoeffsToCoarseAmrLevel (int flev) |
Average coefficients from fine AMR level flev to coarse AMR level flev-1. | |
| void | averageDownCoeffsSameAmrLevel (int amrlev) |
Average coefficients across MG levels within AMR level amrlev. | |
| void | restrictInteriorNodes (int camrlev, MF &crhs, MF &frhs) const |
| Restrict interior-node RHS from fine to coarse when syncing. | |
| void | FillBoundaryCoeff (MF &sigma, const Geometry &geom) |
Fill ghost cells of sigma using geom for BC inference. | |
| void | buildStencil () |
| Build nodal operator stencils reflecting current sigma and metrics. | |
| void | buildIntegral () |
| void | buildSurfaceIntegral () |
| void | setEBInflowVelocity (int amrlev, const MF &eb_vel) |
| bool | supportsAlgMG () const override |
| True if makeAlgMG is implemented for this operator. | |
| void | fillAlgMatrix (int mglev, MFIter const &mfi, Array4< Long const > const &gid, Array4< int const > const &lid, Long *ncols, Long *cols, Real *mat) const override |
| Fill the matrix rows of one box for the algebraic solver. | |
| void | fillRHS (int mglev, MFIter const &mfi, Array4< int const > const &lid, Real *rhs, Array4< Real const > const &bfab) const override |
Fill the right-hand side of the rows of one box on MG level mglev. | |
| template<typename AlgInt, typename AlgGid> | |
| void | fillMatrix_doit (int mglev, MFIter const &mfi, Array4< AlgGid const > const &gid, Array4< int const > const &lid, AlgInt *ncols, AlgInt *cols, Real *mat) const |
| template<typename AlgInt, typename AlgGid> | |
| void | fillMatrix_gpu (int mglev, MFIter const &mfi, Array4< AlgGid const > const &gid, Array4< int const > const &lid, AlgInt *ncols, AlgInt *cols, Real *mat) const |
| template<typename AlgInt, typename AlgGid> | |
| void | fillMatrix_cpu (int mglev, MFIter const &mfi, Array4< AlgGid const > const &gid, Array4< int const > const &lid, AlgInt *ncols, AlgInt *cols, Real *mat) const |
| Public Member Functions inherited from amrex::MLNodeLinOpT< MF > | |
| MLNodeLinOpT () | |
| ~MLNodeLinOpT () override=default | |
| MLNodeLinOpT (const MLNodeLinOpT &)=delete | |
| MLNodeLinOpT (MLNodeLinOpT &&)=delete | |
| MLNodeLinOpT & | operator= (const MLNodeLinOpT &)=delete |
| MLNodeLinOpT & | operator= (MLNodeLinOpT &&)=delete |
| void | define (const Vector< Geometry > &a_geom, const Vector< BoxArray > &a_grids, const Vector< DistributionMapping > &a_dmap, const LPInfo &a_info=LPInfo(), const Vector< FabFactory< FAB > const * > &a_factory={}, int a_eb_limit_coarsening=-1) |
| Bind the nodal operator to an AMR hierarchy. | |
| void | setSmoothNumSweeps (int nsweeps) noexcept |
| Control how many smoother passes are executed inside each Fsmooth call. | |
| void | setLevelBC (int, const MF *, const MF *=nullptr, const MF *=nullptr, const MF *=nullptr) final |
| Set boundary conditions for given level. For cell-centered solves only. | |
| void | apply (int amrlev, int mglev, MF &out, MF &in, BCMode bc_mode, StateMode s_mode, const MLMGBndryT< MF > *bndry=nullptr) const final |
| Apply the nodal operator with the requested BC/state modes. | |
| void | smooth (int amrlev, int mglev, MF &sol, const MF &rhs, bool skip_fillboundary, int niter) const override |
Invoke the nodal smoother on (amrlev,mglev). | |
| void | solutionResidual (int amrlev, MF &resid, MF &x, const MF &b, const MF *crse_bcdata=nullptr) override |
Residual helper that uses solution BCs and optional coarse data (operates on AMR level amrlev). | |
| void | correctionResidual (int amrlev, int mglev, MF &resid, MF &x, const MF &b, BCMode bc_mode, const MF *crse_bcdata=nullptr) override |
Residual helper for correction solves (optionally homogeneous BCs) on (amrlev,mglev). | |
| Vector< RT > | getSolvabilityOffset (int amrlev, int mglev, MF const &rhs) const override |
Return component-wise solvability offsets for (amrlev,mglev, rhs). | |
| void | fixSolvabilityByOffset (int amrlev, int mglev, MF &rhs, Vector< RT > const &offset) const override |
Subtract offsets produced by getSolvabilityOffset() from rhs. | |
| void | prepareForSolve () override |
| Prepare BC caches, masks, and metadata prior to solving. | |
| void | preparePrecond () override |
| Prepare auxiliary data used when the operator acts as a preconditioner. | |
| void | setDirichletNodesToZero (int amrlev, int mglev, MF &mf) const override |
Zero Dirichlet nodes in mf before a correction or residual pass. | |
| bool | isSingular (int amrlev) const override |
Is it singular on AMR level amrlev? | |
| bool | isBottomSingular () const override |
| Is the bottom of the multigrid hierarchy singular? | |
| RT | xdoty (int amrlev, int mglev, const MF &x, const MF &y, bool local) const final |
| Dot-product helper. | |
| RT | dotProductPrecond (Vector< MF const * > const &x, Vector< MF const * > const &y) const final |
| Dot product used when the operator acts as a preconditioner. | |
| RT | norm2Precond (Vector< MF const * > const &x) const final |
| L2 norm used when the operator acts as a preconditioner. | |
| virtual void | applyBC (int amrlev, int mglev, MF &phi, BCMode bc_mode, StateMode state_mode, bool skip_fillboundary=false) const |
| Apply physical BCs prior to smoothing/apply. | |
| void | nodalSync (int amrlev, int mglev, MF &mf) const |
Synchronize nodal values across box/partition boundaries on (amrlev,mglev). | |
| void | buildMasks () |
| Build Dirichlet/dot-product masks and determine bottom singularity. | |
| void | setOversetMask (int amrlev, const iMultiFab &a_dmask) |
| Mark nodes that belong to overset (known) regions. | |
| void | applyOverset (int amrlev, MF &mf) const override |
Zero mf at the known nodes of the overset mask. | |
| RT | normInf (int amrlev, MF const &mf, bool local) const override |
Infinity norm helper operating on level amrlev (set local to true to skip MPI reduction). | |
| void | avgDownResAmr (int, MF &, MF const &) const final |
| Nodal average-down for residuals between AMR levels (no-op here). | |
| void | interpolationAmr (int famrlev, MF &fine, const MF &crse, IntVect const &nghost) const override |
| Prolong AMR-level data during FMG initialization. | |
| void | averageDownAndSync (Vector< MF > &sol) const override |
| Average nodal solutions down the AMR hierarchy and synchronize overlaps. | |
| void | interpAssign (int amrlev, int fmglev, MF &fine, MF &crse) const override |
Overwrite fine data with the prolongation of coarse data (fine = prolong(crse)). | |
| std::unique_ptr< MLAlgMG > | makeAlgMG (int mglev) const override |
Build the algebraic system of MG level mglev of AMR level 0 for the AlgMG solver. Operators that hypre supports implement this. | |
| Public Member Functions inherited from amrex::MLLinOpT< MF > | |
| MLLinOpT ()=default | |
| virtual | ~MLLinOpT ()=default |
| MLLinOpT (const MLLinOpT< MF > &)=delete | |
| MLLinOpT (MLLinOpT< MF > &&)=delete | |
| MLLinOpT< MF > & | operator= (const MLLinOpT< MF > &)=delete |
| MLLinOpT< MF > & | operator= (MLLinOpT< MF > &&)=delete |
| void | define (const Vector< Geometry > &a_geom, const Vector< BoxArray > &a_grids, const Vector< DistributionMapping > &a_dmap, const LPInfo &a_info, const Vector< FabFactory< FAB > const * > &a_factory, bool eb_limit_coarsening=true) |
| Initialize the operator hierarchy on a set of AMR levels. | |
| void | setDomainBC (const Array< BCType, 3 > &lobc, const Array< BCType, 3 > &hibc) noexcept |
| Boundary of the whole domain. | |
| void | setDomainBC (const Vector< Array< BCType, 3 > > &lobc, const Vector< Array< BCType, 3 > > &hibc) |
| Boundary of the whole domain. | |
| void | setDomainBCLoc (const Array< Real, 3 > &lo_bcloc, const Array< Real, 3 > &hi_bcloc) noexcept |
| Set location offsets for the physical domain boundaries. | |
| bool | needsCoarseDataForBC () const noexcept |
| Needs coarse data for bc? | |
| void | setCoarseFineBC (const MF *crse, int crse_ratio, LinOpBCType bc_type=LinOpBCType::Dirichlet) noexcept |
| Set coarse/fine boundary conditions. For cell-centered solves only. | |
| void | setCoarseFineBC (const MF *crse, IntVect const &crse_ratio, LinOpBCType bc_type=LinOpBCType::Dirichlet) noexcept |
| template<typename AMF> requires (!std::same_as<MF,AMF>) | |
| void | setCoarseFineBC (const AMF *crse, int crse_ratio, LinOpBCType bc_type=LinOpBCType::Dirichlet) noexcept |
| template<typename AMF> requires (!std::same_as<MF,AMF>) | |
| void | setCoarseFineBC (const AMF *crse, IntVect const &crse_ratio, LinOpBCType bc_type=LinOpBCType::Dirichlet) noexcept |
| template<MultiFabLike AMF> requires (!std::same_as<MF,AMF>) | |
| void | setLevelBC (int amrlev, const AMF *levelbcdata, const AMF *robinbc_a=nullptr, const AMF *robinbc_b=nullptr, const AMF *robinbc_f=nullptr) |
| void | setVerbose (int v) noexcept |
| Set verbosity. | |
| void | setPrintIndentation (std::string s) |
| Prefix printed messages (e.g., to indent per level). | |
| void | setMaxOrder (int o) noexcept |
| Set order of interpolation at coarse/fine boundary. | |
| int | getMaxOrder () const noexcept |
| Get order of interpolation at coarse/fine boundary. | |
| void | setEnforceSingularSolvable (bool o) noexcept |
| Control whether the solver should try to make singular problems solvable. | |
| bool | getEnforceSingularSolvable () const noexcept |
| virtual bool | supportCustomBottomSolver () const |
| Does this operator provide its own bottom solver (BottomSolver::custom)? | |
| virtual void | customBottomSolve (MLMGT< MF > *mlmg, MF &x, const MF &b, RT eps_rel, RT eps_abs, int maxiter) |
| Bottom solve provided by the operator itself. | |
| virtual int | getNComp () const |
| Return number of components. | |
| virtual int | getNGrow (int=0, int=0) const |
| virtual void | prepareForFluxes (int amrlev, const MF *crse_bcdata=nullptr) |
| Ensure BC caches are populated before flux extraction. | |
| virtual void | compFlux (int amrlev, const Array< MF *, 3 > &fluxes, MF &sol, Location loc) const |
| Compute fluxes. | |
| virtual void | applyMetricTerm (int amrlev, int mglev, MF &rhs) const |
Apply metric scaling to the RHS on (amrlev,mglev). | |
| virtual void | unapplyMetricTerm (int amrlev, int mglev, MF &rhs) const |
| Remove metric scaling previously applied via applyMetricTerm(). | |
| virtual void | applyInhomogNeumannTerm (int amrlev, MF &rhs) const |
| Add extra terms introduced when treating inhomogeneous Neumann BC as homogeneous. | |
| virtual bool | scaleRHS (int amrlev, MF *rhs) const |
| Optionally scale the RHS to fix solvability. | |
| virtual std::unique_ptr< MLLinOpT< MF > > | makeNLinOp (int grid_size) const |
| Create the NSolve counterpart of this operator with the requested grid size. | |
| virtual void | getEBFluxes (const Vector< MF * > &a_flux, const Vector< MF * > &a_sol) const |
| Extract embedded-boundary fluxes. | |
| virtual bool | supportsAnisotropicCoarsening () const |
| True if the operator supports MG levels coarsened in any subset of directions. Then MLMG coarsens stretched cells only in their short directions until they are nearly cubic. | |
| virtual GpuArray< Real, 3 > | anisotropicCoarseningCellSize (Geometry const &geom) const |
| Cell size used to pick the directions to coarsen when supportsAnisotropicCoarsening() is true. A direction with weaker coupling counts as having longer cells. | |
| virtual bool | supportNSolve () const |
| Whether this operator supports NSolve. | |
| bool | isMixedPrecision () const noexcept |
| True if this operator has a single precision copy for mixed precision. | |
| virtual void | copyNSolveSolution (MF &dst, MF const &src) const |
Copy an NSolve solution from src to dst. | |
| virtual void | postSolve (Vector< MF * > const &sol) const |
| Optional hook invoked after the main solve completes. | |
| virtual void | avgDownResMG (int clev, MF &cres, MF const &fres) const |
| Average residuals from fine to coarse MG levels (FMG helper). | |
| virtual void | beginPrecondBC () |
| Called when the operator starts being used as a preconditioner. | |
| virtual void | endPrecondBC () |
| Called when the operator stops being used as a preconditioner. | |
| bool | isMFIterSafe (int amrlev, int mglev1, int mglev2) const |
| Check whether mixing MFIter loops for different MG levels is safe. | |
| int | NAMRLevels () const noexcept |
| Return the number of AMR levels. | |
| int | NMGLevels (int amrlev) const noexcept |
| Return the number of MG levels at given AMR level. | |
| const Geometry & | Geom (int amr_lev, int mglev=0) const noexcept |
Geometry accessor for (amr_lev,mglev). | |
Protected Member Functions | |
| void | spCopySettings () override |
| void | resizeMultiGrid (int new_size) final |
| void | spUpdateScale () noexcept |
| EBFArrayBoxFactory const * | ebFactory (int amrlev) const |
| Protected Member Functions inherited from amrex::MLNodeLinOpT< MF > | |
| void | spCopySettings () override |
| void | resizeMultiGrid (int new_size) override |
| void | buildMGHierarchy () override |
| Build the MG levels of AMR level 0 below the finest one. | |
| Protected Member Functions inherited from amrex::MLLinOpT< MF > | |
| int | spMetricExponent () const noexcept |
| Vector< Geometry > | spGeom (const Vector< Geometry > &a_geom) |
| LPInfo | dpInfo (LPInfo const &a_info) const |
| template<typename F> | |
| void | makeSPLinOp (LPInfo const &a_info, F const &f) |
| template<template< typename > class Op, typename F> | |
| void | spForward (F const &f) |
| const Vector< int > & | AMRRefRatio () const noexcept |
| Return AMR refinement ratios. | |
| int | AMRRefRatio (int amr_lev) const noexcept |
| Return AMR refinement ratio at given AMR level. | |
| IntVect | AMRRefRatioVect (int amr_lev) const noexcept |
| Return AMR refinement ratio as IntVect (1 in hidden direction). | |
| FabFactory< FAB > const * | Factory (int amr_lev, int mglev=0) const noexcept |
| GpuArray< BCType, 3 > | LoBC (int icomp=0) const noexcept |
| GpuArray< BCType, 3 > | HiBC (int icomp=0) const noexcept |
| bool | hasBC (BCType bct) const noexcept |
| bool | hasInhomogNeumannBC () const noexcept |
| bool | hasRobinBC () const noexcept |
| virtual bool | supportRobinBC () const noexcept |
| virtual bool | supportInhomogNeumannBC () const noexcept |
| bool | isBottomActive () const noexcept |
| MPI_Comm | BottomCommunicator () const noexcept |
| MPI_Comm | Communicator () const noexcept |
| void | setCoarseFineBCLocation (const RealVect &cloc) noexcept |
| bool | doAgglomeration () const noexcept |
| bool | doConsolidation () const noexcept |
| bool | doSemicoarsening () const noexcept |
| bool | isCellCentered () const noexcept |
| virtual IntVect | getNGrowVectRestriction () const |
| virtual void | make (Vector< Vector< MF > > &mf, IntVect const &ng) const |
| virtual MF | make (int amrlev, int mglev, IntVect const &ng) const |
| virtual MF | make (int amrlev, int mglev, IntVect const &ng, MFInfo const &mf_info) const |
| As above, with caller-selected allocation metadata for temporary storage. | |
| virtual MF | makeAlias (MF const &mf) const |
| virtual MF | makeCoarseMG (int amrlev, int mglev, IntVect const &ng) const |
Allocate an MF on the next coarser MG level (mglev+1) with grow cells ng. | |
| virtual MF | makeCoarseMG (int amrlev, int mglev, IntVect const &ng, MFInfo const &mf_info) const |
| As above, with caller-selected allocation metadata for temporary storage. | |
| virtual MF | makeCoarseAmr (int famrlev, IntVect const &ng) const |
Allocate an MF on the next coarser AMR level (famrlev-1) with grow cells ng. | |
| virtual MF | makeCoarseAmr (int famrlev, IntVect const &ng, MFInfo const &mf_info) const |
| As above, with caller-selected allocation metadata for temporary storage. | |
| virtual std::unique_ptr< FabFactory< FAB > > | makeFactory (int, int) const |
| void | prepareMGHierarchy () |
| Build the deferred MG levels of AMR level 0 once. See supportsAnisotropicCoarsening. | |
| bool | hasHiddenDimension () const noexcept |
| int | hiddenDirection () const noexcept |
| Box | compactify (Box const &b) const noexcept |
| template<typename T> | |
| Array4< T > | compactify (Array4< T > const &a) const noexcept |
| template<typename T> | |
| T | get_d0 (T const &dx, T const &dy, T const &) const noexcept |
| template<typename T> | |
| T | get_d1 (T const &, T const &dy, T const &dz) const noexcept |
Static Protected Member Functions | |
| static MF const * | ebVolFrac (EBFArrayBoxFactory const *f) |
| Volume fraction of EB factory f, or nullptr. | |
| Static Protected Member Functions inherited from amrex::MLNodeLinOpT< MF > | |
| static GpuArray< RT, 3 > | toRT (GpuArray< Real, 3 > const &a) noexcept |
| Convert a geometry array to RT. | |
| Static Protected Member Functions inherited from amrex::MLLinOpT< MF > | |
| static RT | spScaleFor (RT x) noexcept |
| The power of two p with p*x in [0.5,1), or 1 if x is zero or not finite. | |
| static RT | spDiagForScale (Vector< RT > const &diag) noexcept |
Friends | |
| class | HypreMLNodeLap |
| using amrex::MLNodeLaplacianT< MF >::BCMode = typename MLNodeLinOpT<MF>::BCMode |
| using amrex::MLNodeLaplacianT< MF >::CoarseningStrategy = typename MLNodeLinOpT<MF>::CoarseningStrategy |
| using amrex::MLNodeLaplacianT< MF >::FAB = typename MLNodeLinOpT<MF>::FAB |
| using amrex::MLNodeLaplacianT< MF >::Location = typename MLNodeLinOpT<MF>::Location |
| using amrex::MLNodeLaplacianT< MF >::RT = typename MLNodeLinOpT<MF>::RT |
| using amrex::MLNodeLaplacianT< MF >::StateMode = typename MLNodeLinOpT<MF>::StateMode |
|
default |
Construct an empty operator; call define() before solving.
| amrex::MLNodeLaplacianT< MF >::MLNodeLaplacianT | ( | const Vector< Geometry > & | a_geom, |
| const Vector< BoxArray > & | a_grids, | ||
| const Vector< DistributionMapping > & | a_dmap, | ||
| const LPInfo & | a_info = LPInfo(), | ||
| const Vector< FabFactory< FAB > const * > & | a_factory = {}, | ||
| RT | a_const_sigma = RT(0.0) ) |
Convenience constructor without EB factories.
| a_geom | Per-level geometries. |
| a_grids | Per-level grids. |
| a_dmap | Distribution mappings. |
| a_info | LPInfo overrides. |
| a_factory | Optional nodal factories per level. |
| a_const_sigma | Uniform conductivity. Zero selects variable conductivity; setSigma() must then supply nonzero coefficients. |
| amrex::MLNodeLaplacianT< MF >::MLNodeLaplacianT | ( | const Vector< Geometry > & | a_geom, |
| const Vector< BoxArray > & | a_grids, | ||
| const Vector< DistributionMapping > & | a_dmap, | ||
| const LPInfo & | a_info, | ||
| const Vector< EBFArrayBoxFactory const * > & | a_factory, | ||
| RT | a_const_sigma = RT(0.0) ) |
Convenience constructor that accepts embedded-boundary factories.
|
overridedefault |
|
delete |
|
delete |
| void amrex::MLNodeLaplacianT< MF >::averageDownCoeffs | ( | ) |
Average conductivity down across all AMR and MG levels.
| void amrex::MLNodeLaplacianT< MF >::averageDownCoeffsSameAmrLevel | ( | int | amrlev | ) |
Average coefficients across MG levels within AMR level amrlev.
| void amrex::MLNodeLaplacianT< MF >::averageDownCoeffsToCoarseAmrLevel | ( | int | flev | ) |
Average coefficients from fine AMR level flev to coarse AMR level flev-1.
|
finalvirtual |
Average solution/RHS pairs from fine AMR levels onto (camrlev).
Reimplemented from amrex::MLLinOpT< MF >.
| template void amrex::MLNodeLaplacianT< MF >::buildIntegral | ( | ) |
| template void amrex::MLNodeLaplacianT< MF >::buildStencil | ( | ) |
Build nodal operator stencils reflecting current sigma and metrics.
| template void amrex::MLNodeLaplacianT< MF >::buildSurfaceIntegral | ( | ) |
| void amrex::MLNodeLaplacianT< MF >::compDivergence | ( | const Vector< MF * > & | rhs, |
| const Vector< MF * > & | vel ) |
Compute rhs = div(vel) on nodal grids (used for projections).
|
inlinefinalvirtual |
Unsupported flux-style gradient extractor (kept for interface completeness).
| amrlev | AMR level index (ignored). |
| grad | Destination MultiFabs (ignored). |
| sol | Solution hierarchy (ignored). |
| loc | Requested location (ignored). |
Reimplemented from amrex::MLLinOpT< MF >.
| void amrex::MLNodeLaplacianT< MF >::compGrad | ( | int | amrlev, |
| MF & | grad, | ||
| MF & | sol ) const |
| void amrex::MLNodeLaplacianT< MF >::compRHS | ( | const Vector< MF * > & | rhs, |
| const Vector< MF * > & | vel, | ||
| const Vector< const MF * > & | rhnd, | ||
| const Vector< MF * > & | rhcc ) |
Assemble RHS including nodal/cell-centered forcing terms.
| template void amrex::MLNodeLaplacianT< MF >::compSyncResidualCoarse | ( | MF & | sync_resid, |
| const MF & | phi, | ||
| const MF & | vold, | ||
| const MF * | rhcc, | ||
| const BoxArray & | fine_grids, | ||
| const IntVect & | ref_ratio ) |
Build coarse-level sync residuals for multilevel projections.
| template void amrex::MLNodeLaplacianT< MF >::compSyncResidualFine | ( | MF & | sync_resid, |
| const MF & | phi, | ||
| const MF & | vold, | ||
| const MF * | rhcc ) |
Build fine-level sync residuals for multilevel projections.
| void amrex::MLNodeLaplacianT< MF >::define | ( | const Vector< Geometry > & | a_geom, |
| const Vector< BoxArray > & | a_grids, | ||
| const Vector< DistributionMapping > & | a_dmap, | ||
| const LPInfo & | a_info, | ||
| const Vector< EBFArrayBoxFactory const * > & | a_factory, | ||
| RT | a_const_sigma = RT(0.0) ) |
| void amrex::MLNodeLaplacianT< MF >::define | ( | const Vector< Geometry > & | a_geom, |
| const Vector< BoxArray > & | a_grids, | ||
| const Vector< DistributionMapping > & | a_dmap, | ||
| const LPInfo & | a_info = LPInfo(), | ||
| const Vector< FabFactory< FAB > const * > & | a_factory = {}, | ||
| RT | a_const_sigma = RT(0.0) ) |
Bind the nodal operator (no EB data).
| a_geom | Per-level geometries. |
| a_grids | Per-level grids. |
| a_dmap | Distribution mappings. |
| a_info | LPInfo overrides. |
| a_factory | Optional nodal factories per level. |
| a_const_sigma | Uniform conductivity. Zero selects variable conductivity; setSigma() must then supply nonzero coefficients. |
|
inlinenodiscardprotected |
EB factory of AMR level amrlev, or nullptr. EB data are double precision, so the float operator never has one.
|
inlinestaticnodiscardprotected |
Volume fraction of EB factory f, or nullptr.
|
finalvirtual |
Apply the nodal Laplacian to in at (amrlev,mglev).
Implements amrex::MLNodeLinOpT< MF >.
|
overridevirtual |
Fill the matrix rows of one box for the algebraic solver.
Same packed layout as the Hypre version: ncols[lid] entries per row, diagonal first, neighbors without a row dropped. The MG level is on AMR level 0. Global row ids are numeric_limits<Long>::max() and local ids negative where there is no row.
Reimplemented from amrex::MLNodeLinOpT< MF >.
| void amrex::MLNodeLaplacianT< MF >::FillBoundaryCoeff | ( | MF & | sigma, |
| const Geometry & | geom ) |
Fill ghost cells of sigma using geom for BC inference.
| void amrex::MLNodeLaplacianT< MF >::fillMatrix_cpu | ( | int | mglev, |
| MFIter const & | mfi, | ||
| Array4< AlgGid const > const & | gid, | ||
| Array4< int const > const & | lid, | ||
| AlgInt * | ncols, | ||
| AlgInt * | cols, | ||
| Real * | mat ) const |
| void amrex::MLNodeLaplacianT< MF >::fillMatrix_doit | ( | int | mglev, |
| MFIter const & | mfi, | ||
| Array4< AlgGid const > const & | gid, | ||
| Array4< int const > const & | lid, | ||
| AlgInt * | ncols, | ||
| AlgInt * | cols, | ||
| Real * | mat ) const |
| void amrex::MLNodeLaplacianT< MF >::fillMatrix_gpu | ( | int | mglev, |
| MFIter const & | mfi, | ||
| Array4< AlgGid const > const & | gid, | ||
| Array4< int const > const & | lid, | ||
| AlgInt * | ncols, | ||
| AlgInt * | cols, | ||
| Real * | mat ) const |
|
overridevirtual |
Fill the right-hand side of the rows of one box on MG level mglev.
Reimplemented from amrex::MLNodeLinOpT< MF >.
|
overridevirtual |
Subtract solvability offsets from rhs.
Reimplemented from amrex::MLLinOpT< MF >.
|
finalvirtual |
Adjust residual masks so EB Dirichlet nodes remain constrained.
Reimplemented from amrex::MLNodeLinOpT< MF >.
|
finalvirtual |
Execute the smoother on (amrlev,mglev).
| amrlev | AMR level index. |
| mglev | Multigrid level index. |
| sol | Correction updated in place. |
| rhs | RHS supplied to the smoother. |
Implements amrex::MLNodeLinOpT< MF >.
|
inlinenodiscardfinalvirtual |
Reimplemented from amrex::MLLinOpT< MF >.
|
inlinefinalvirtual |
This overload is unused for nodal Laplacians (only cell-centered flux extraction is supported).
| a_flux | Destination arrays (ignored). |
| a_sol | Solution hierarchy (ignored). |
| a_loc | Requested location (ignored). |
Reimplemented from amrex::MLLinOpT< MF >.
|
finalvirtual |
Compute face-centered fluxes given nodal solutions.
Reimplemented from amrex::MLLinOpT< MF >.
|
overridevirtual |
Compute component-wise offsets needed for solvability enforcement.
Reimplemented from amrex::MLLinOpT< MF >.
|
finalvirtual |
Set the coarse/fine nodes of fine AMR level famrlev (Dirichlet mask set, not on a Dirichlet domain face) to the interpolated coarse solution, so that the composite solution does not depend on the initial guess there. Known nodes of an overset mask are kept.
| famrlev | Fine AMR level index. |
| fine_sol | Fine solution, modified at the coarse/fine nodes. |
| crse_sol | Coarse solution. |
Reimplemented from amrex::MLLinOpT< MF >.
|
finalvirtual |
Add the prolongation of coarse data onto the fine grid (fine += prolong(crse)).
Implements amrex::MLLinOpT< MF >.
|
inlinenodiscardoverridevirtual |
Reimplemented from amrex::MLLinOpT< MF >.
|
inlinenodiscardfinalvirtual |
True if sigma-derived data need to be refreshed before reuse.
Reimplemented from amrex::MLLinOpT< MF >.
|
finalvirtual |
Divide mf by the diagonal of the operator (used by CG-family bottom solvers).
Reimplemented from amrex::MLLinOpT< MF >.
|
delete |
|
delete |
|
finalvirtual |
Finalize metric terms, sigma averages, and BC caches before solving.
Implements amrex::MLLinOpT< MF >.
|
finalvirtual |
Flux register reflux coupling coarse/fine nodal solves (updates res using the solution and RHS arrays on both levels).
Reimplemented from amrex::MLLinOpT< MF >.
|
finalprotectedvirtual |
Reimplemented from amrex::MLLinOpT< MF >.
| void amrex::MLNodeLaplacianT< MF >::restrictInteriorNodes | ( | int | camrlev, |
| MF & | crhs, | ||
| MF & | frhs ) const |
Restrict interior-node RHS from fine to coarse when syncing.
|
finalvirtual |
Restrict nodal data from fine grids to coarse MG level cmglev.
Implements amrex::MLLinOpT< MF >.
|
inlinenoexcept |
Second-order nodal divergence at nodes on Neumann and inflow domain faces.
By default, compRHS is first order at these nodes (walls and inflow faces): it takes the tangential velocity, and the cell-centered source, of the first layer of cells as constant over the node's half control volume. After a projection, the normal velocity in the cells next to the face is then off by (h^2/8) d^2u_n/dn^2. A cell-centered viscous operator (MLABecLaplacian, MLTensorOp) with a Dirichlet condition on the face turns this into an O(1) error in the normal component. With this option, both terms are taken a quarter cell from the face instead, extrapolated linearly from the first two layers of cells, in each such direction at domain edges and corners. The ghost cells must hold the normal velocity on the face, as compRHS already assumes.
Not supported with RZ (compRHS aborts if setRZCorrection(true) is also set). Not applied at coarse/fine nodes or in the sync residual. With EB, applied only at nodes whose nearby cells (two layers and the ghost cells, on both sides) are all regular. Without a source the discrete volume balance is unchanged; with one, the corrected right-hand side differs from the integral of the source by O(h^2). See Tests/LinearSolvers/NodalProjectionWall.
| on | false (the default): the original stencil. true: the correction. |
|
inlinenoexcept |
Pick between sigma-weighted or RAP coarsening (ignored if sigma constant).
| cs | Desired coarsening strategy enum. |
| void amrex::MLNodeLaplacianT< MF >::setEBInflowVelocity | ( | int | amrlev, |
| const MF & | eb_vel ) |
|
inlinenoexcept |
Choose red-black Gauss-Seidel instead of Jacobi smoothing.
| flag | True selects Gauss-Seidel. |
|
inlinenoexcept |
Toggle harmonic averaging when coarsening sigma.
| flag | True enables harmonic averaging. |
|
inlinenoexcept |
Enable mapped-coordinate metrics (non-orthogonal grids).
| flag | True enables mapped-coordinate support. |
|
inlinenoexcept |
Threshold for normalization (prevents dividing by tiny averages).
| t | Minimum average magnitude allowed before rescaling. |
|
inlinenoexcept |
Enable cylindrical (RZ) metric terms.
| rz | True activates RZ corrections. |
| void amrex::MLNodeLaplacianT< MF >::setSigma | ( | int | amrlev, |
| const MF & | a_sigma ) |
|
inlineoverrideprotectedvirtual |
Mixed precision: give a new single precision copy the settings made on this operator before define, which define keeps.
Reimplemented from amrex::MLLinOpT< MF >.
| void amrex::MLNodeLaplacianT< MF >::spForwardSigma | ( | ) |
Mixed precision: send sigma, scaled, to the single precision copy. Public for CUDA.
|
inlineprotectednoexcept |
Mixed precision: the copy's sigma is m_sp_sigma_scale times ours and its lengths m_sp_length_scale times ours. The RZ terms do not depend on the length.
|
inlinenodiscardoverridevirtual |
True if makeAlgMG is implemented for this operator.
Reimplemented from amrex::MLLinOpT< MF >.
|
inlinenodiscardoverridevirtual |
Mixed precision: true only for the exact operator types that build a single precision copy of themselves, not for classes derived from them.
Reimplemented from amrex::MLLinOpT< MF >.
|
finalvirtual |
Remove Neumann contributions previously imposed on rhs.
Reimplemented from amrex::MLLinOpT< MF >.
|
finalvirtual |
Refresh sigma averages/stencils and clear the dirty flag.
Reimplemented from amrex::MLLinOpT< MF >.
| void amrex::MLNodeLaplacianT< MF >::updateVelocity | ( | const Vector< MF * > & | vel, |
| const Vector< MF const * > & | sol ) const |
Update velocities using the Poisson solution (projection correction).
|
friend |
 1.15.0